
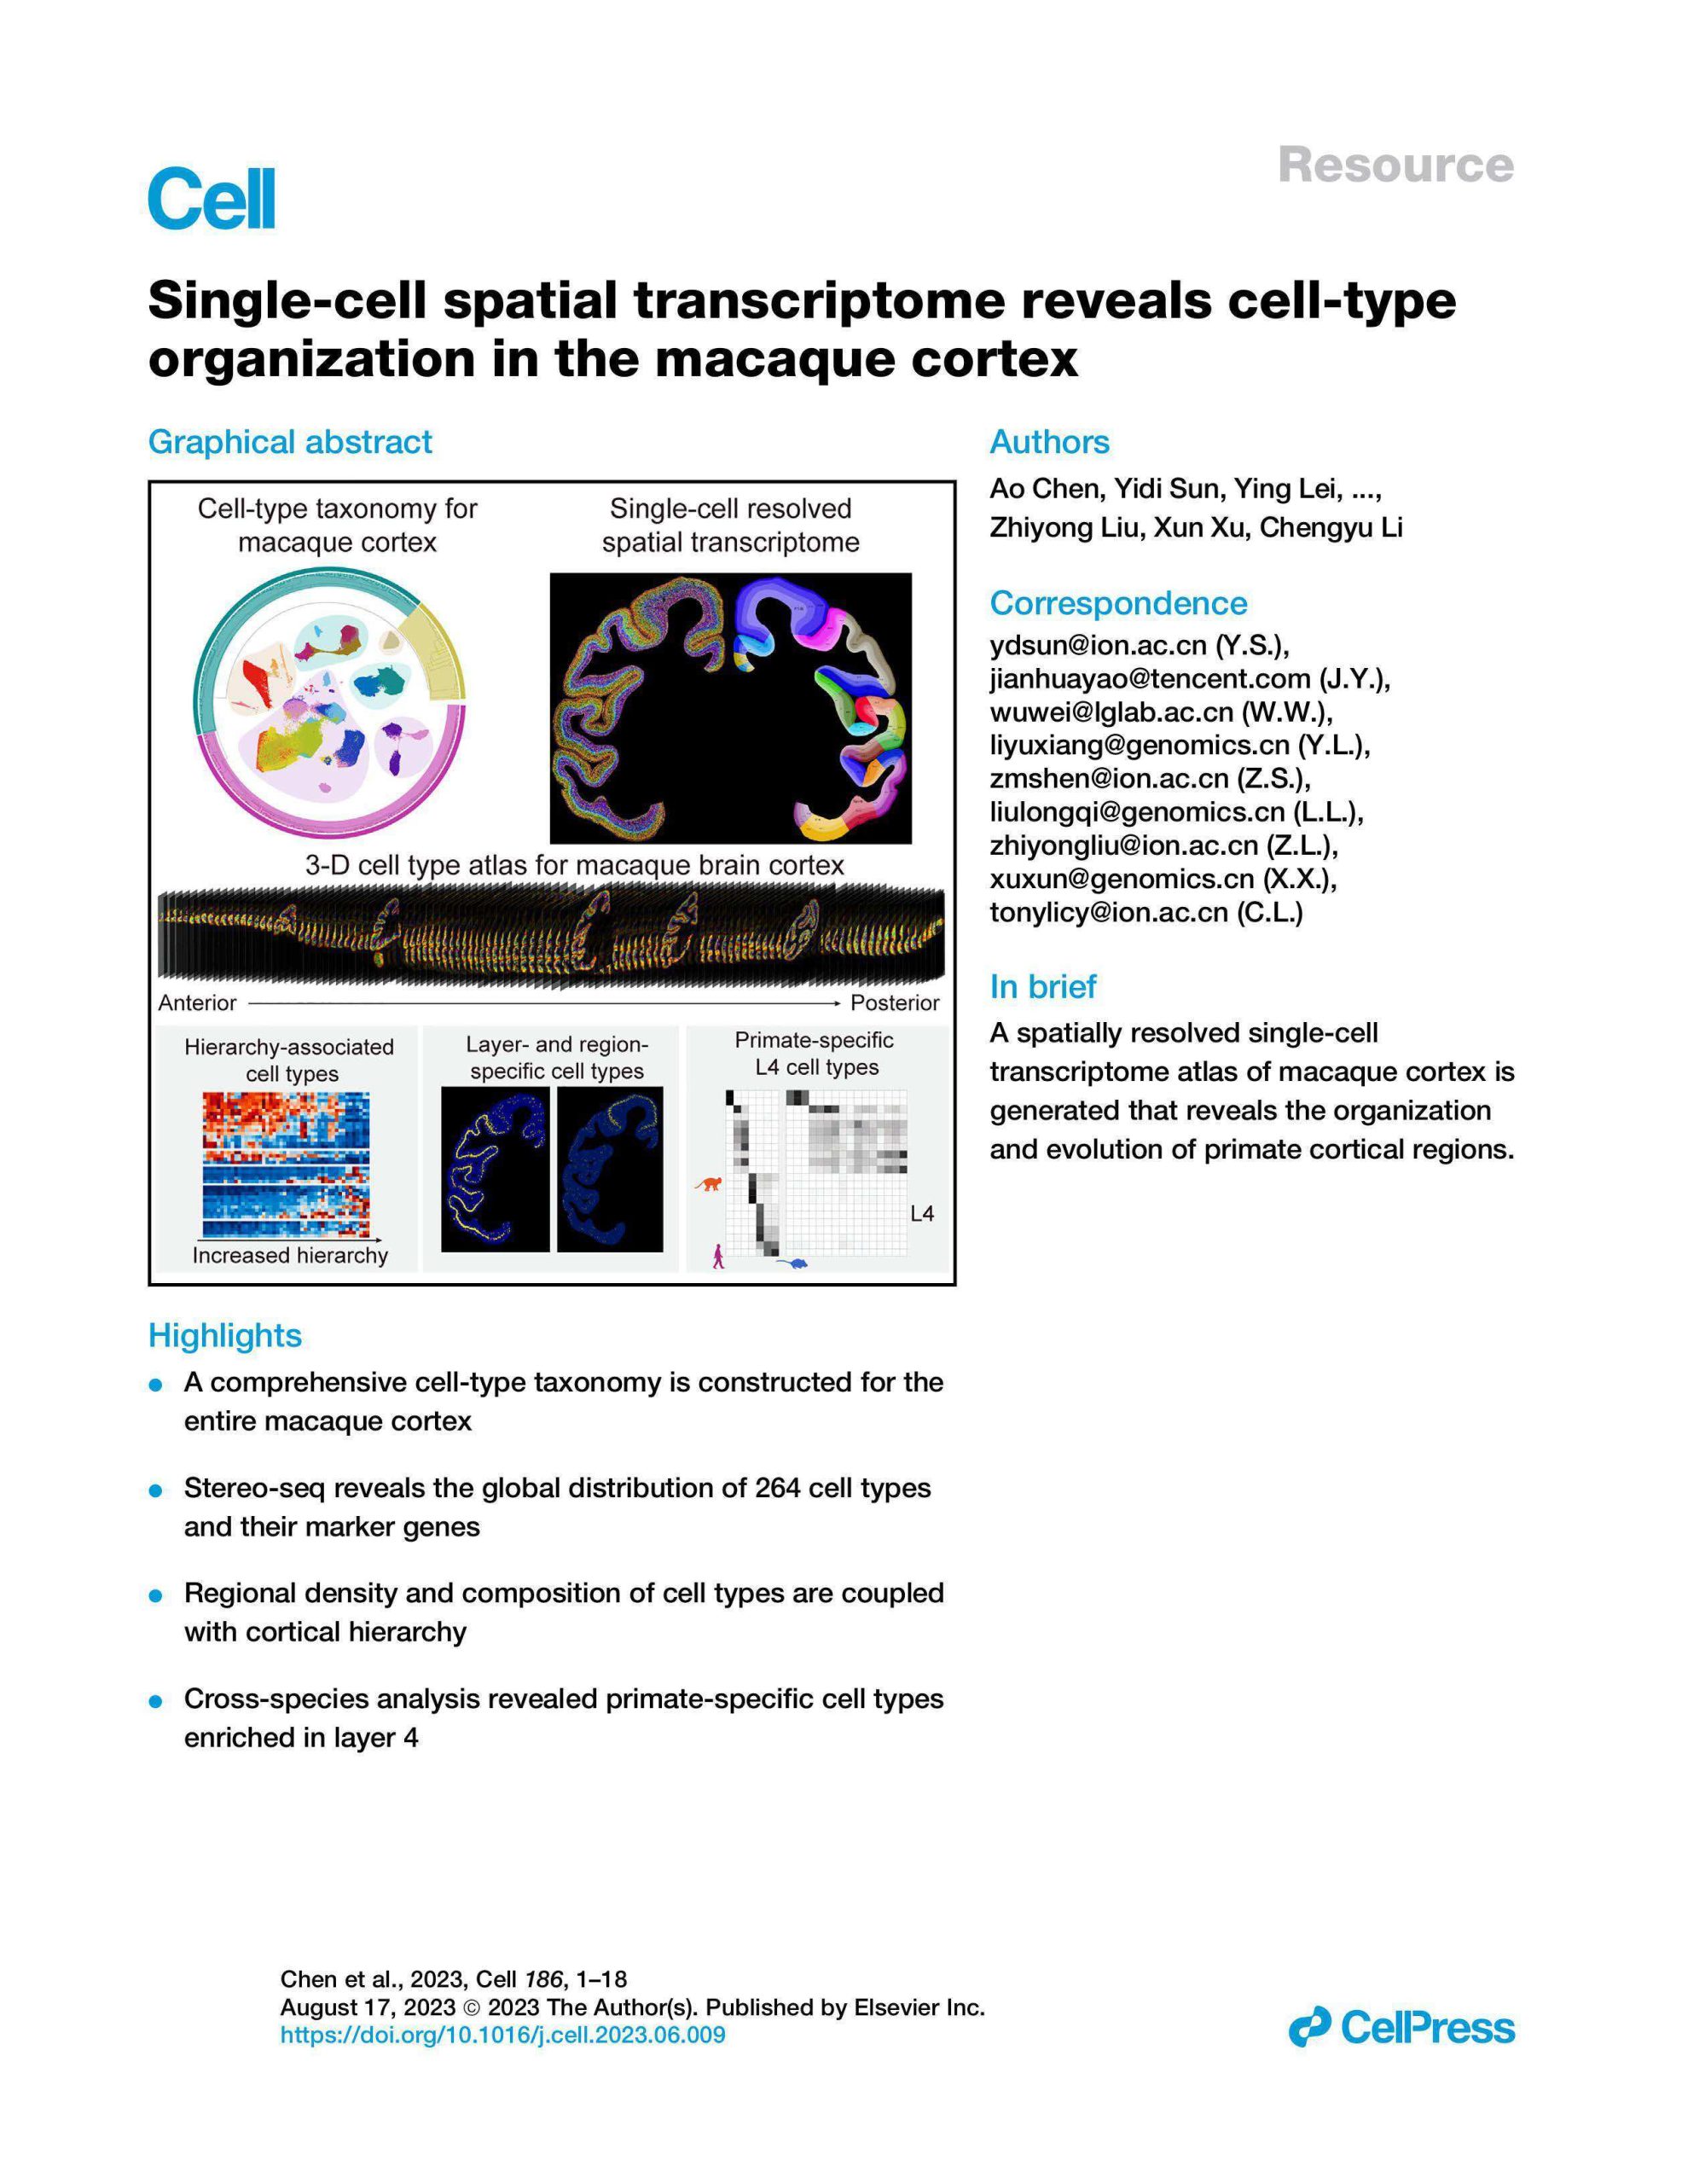
Tracing the messy start — real lab moments and hard numbers
I once arrived at 08:30 on a humid March morning in Penang and found the whole antibody rack mislabeled — classic morning lah — and that small error cost us a 27% drop in target detection on our Stereo-seq pilot. In that same run I logged the raw counts, compared UMI collapse rates, and asked: with a 27% loss and a two-day rework, how can we trust published sensitivity claims? Early on, I focus on spatial proteomics because it shows where the problem really lives (sample prep, not just software).
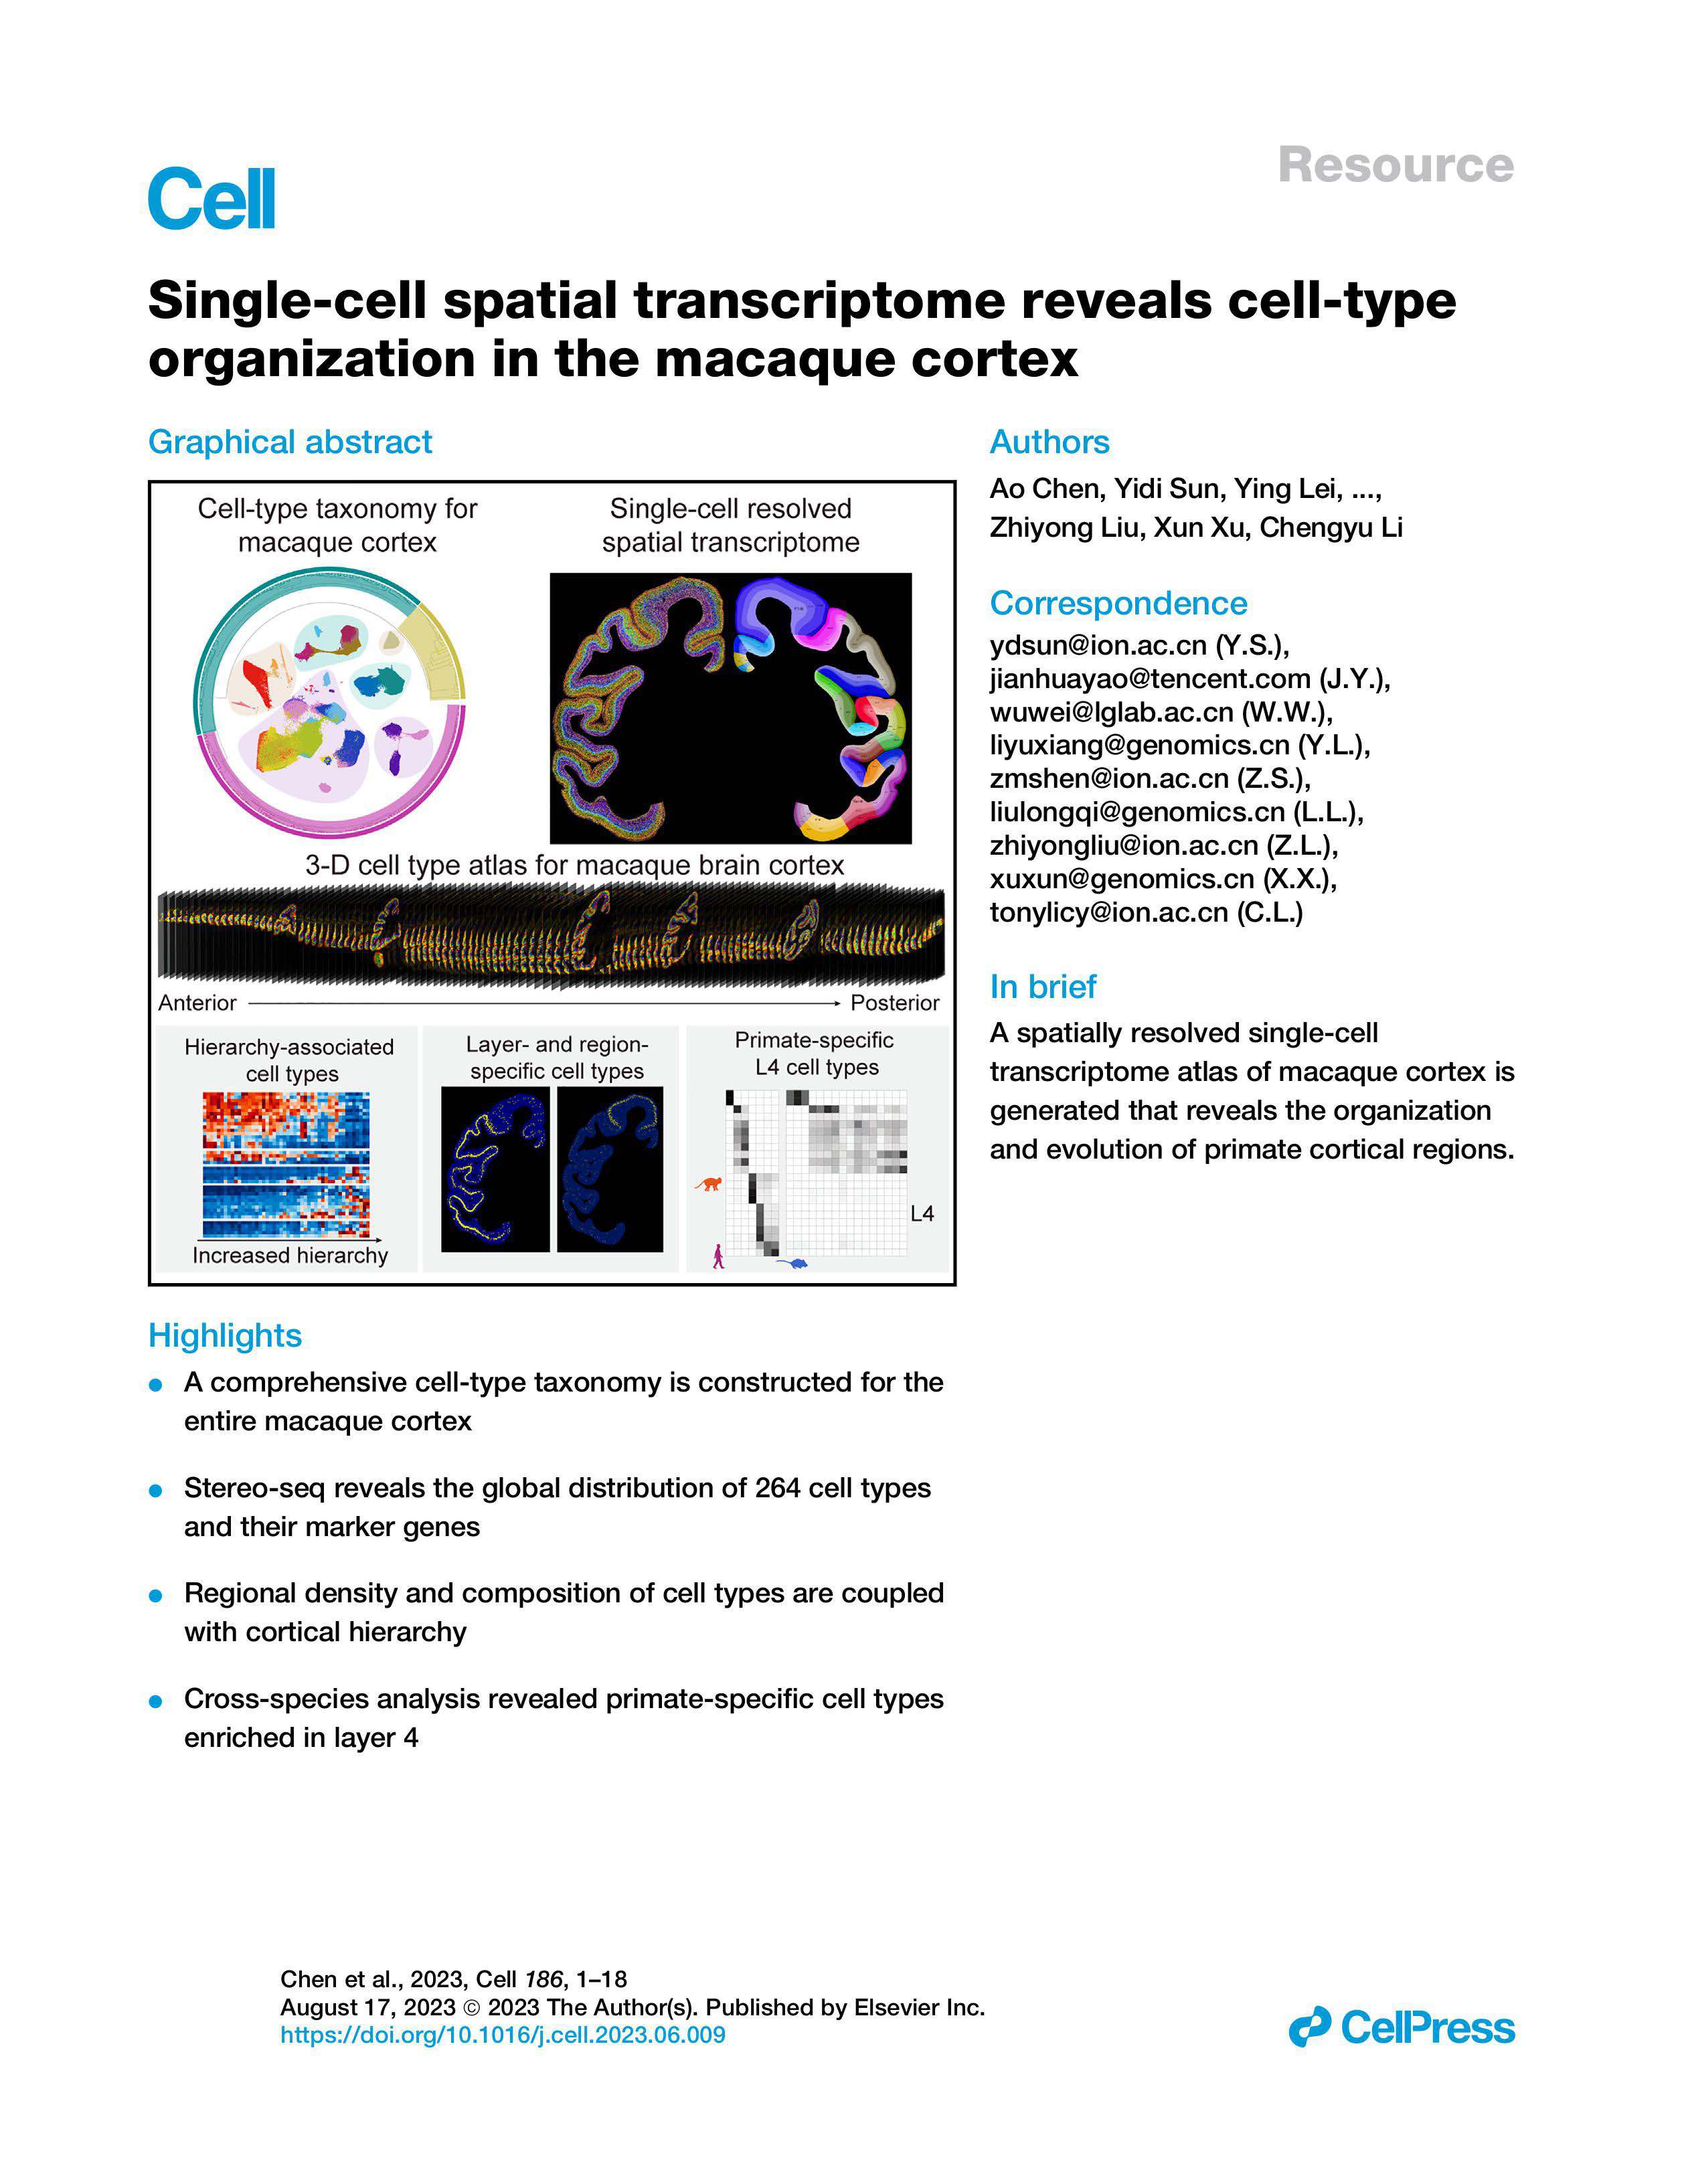
I have over 15 years working with lab teams — I remember a June 2023 tissue sectioning session at University Malaya where a single 8 µm slice saved us time but later caused uneven staining. That taught me two things: the user pain points are often mundane (bad mounting, wrong antibody panel) and traditional fixes (more replicates, longer incubation) cost time and budget without addressing root causes. We use terms like antibody panel, tissue sectioning, multiplexing, and spatial resolution not as buzzwords but as levers — when one lever is off, throughput stalls. Short story: the visible problem is rarely the deepest problem; the hidden pain is process fragility, and it hurts reproducibility (and morale) badly. — I mean really badly.
From diagnosis to design — a technical look ahead
Let me define a simple view: efficiency = reliable output per lab-hour. Here, reliability depends on four things — sample integrity, antibody specificity, image registration accuracy, and data normalization. When we apply that lens to spatial proteomics, the failure modes shift from abstract algorithms to physical steps: poor tissue sectioning, inconsistent blocking, and antibody cross-reactivity. I prefer to measure early and often — quick QC on slides at t=0, a 15-minute check that saves days later. In my experience, one well-planned pilot with defined acceptance thresholds cut downstream rework by over 40% (we logged the metric in July 2022 during a lung biopsy study). This is not theory; it’s hands-on troubleshooting with concrete numbers.
What’s Next?
Looking forward, compare platforms by three practical metrics I always use: 1) true spatial resolution under real sample conditions (not vendor slides), 2) end-to-end reproducibility measured as variance in detected protein counts across three independent runs, and 3) total hands-on time per sample including QC and rework. These are simple, measurable, and they focus on the pain points we fixed in the past. I recommend running a small comparative pilot — same tissue, same antibody panel, three runs — and scoring each system on those metrics. Then pick the one that consistently hits thresholds. Oh — and do not ignore supply chain details; lead time for antibodies once caused a two-week delay during a project in KL last year (not fun). I still prefer straightforward checks; they save you resource headache later. (boleh trust this)
To close, I offer three quick evaluation metrics you can apply now: operational repeatability (CV of protein counts), effective spatial fidelity (measured in microns on real tissue), and total process time (hours per sample including QC). Use those to decide, and you’ll move from reactive fixes to predictable results. For anyone wanting a practical partner on this journey, I often point colleagues to tooling and services from stomics — their platform was part of the Stereo-seq run I mentioned above — but the core decision stays yours. I’ll pause — think about your last run — what metric surprised you most?